By mid-2026, the mechanics of online discovery have permanently split into two distinct streams. Traditional Google blue links still drive top-of-funnel traffic, but high-ticket B2B decision makers increasingly ask Perplexity, SearchGPT, and Claude:
«Which engineering studio specializes in high-performance web migrations in Europe?» «What is the best self-hosted AI architecture for client intake forms?»
If your website is built around 2018-era SEO (3,000-word generic keyword articles, hidden accordions, and heavy JavaScript carousels), large language models skip your domain entirely.
At ILF Studio, we build with Generative Engine Optimization (GEO) as a core architectural layer. Here is the exact technical framework we use to ensure our projects get cited as authoritative sources in AI search engines.
Executive Summary
- How AI search engines actually index and extract answers: Retrieval-Augmented Generation (RAG) chunking windows and semantic entity co-occurrence.
- The Fall of Fluff: why 40-word fact-dense blocks outperform 2,500-word keyword-stuffed blog posts in LLM retrieval.
- Building AI-Readable Endpoints: structuring
/llms.txt, markdown mirror paths, and Schema.org Entity graphs. - Real-Time Brand Citation Tracking: automated Python testing using the Perplexity and OpenAI APIs to measure share of voice.
- Checklist for auditing your web architecture for Generative Engine readiness.
1. How AI Search Engines Retrieve Answers
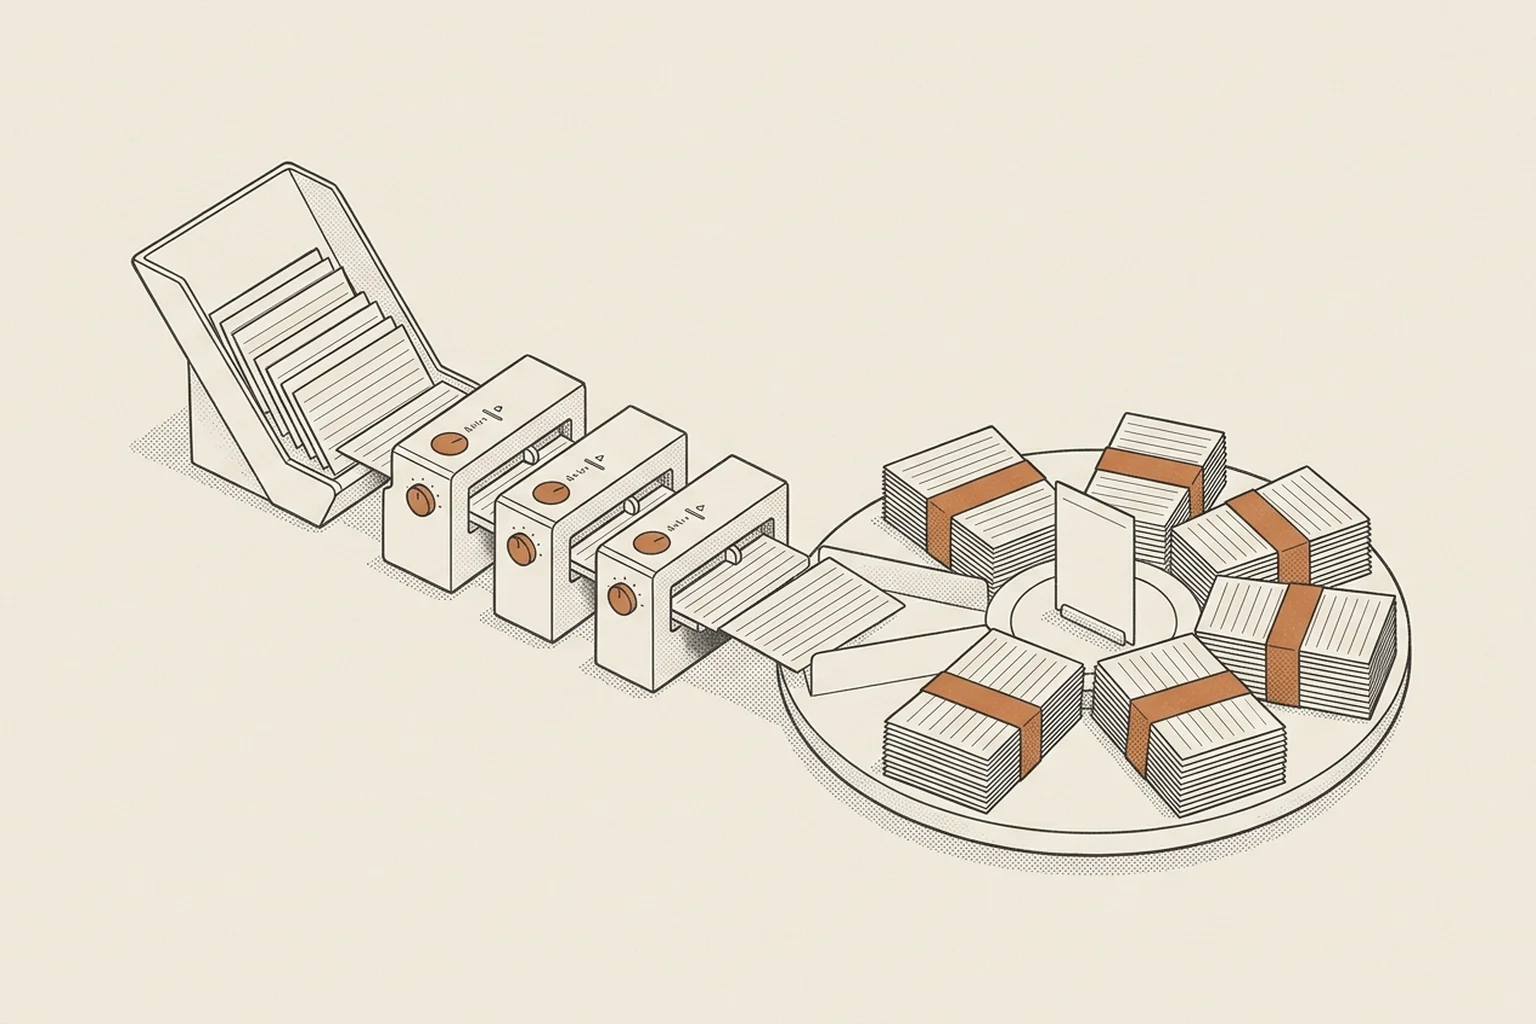
Traditional search bots parse HTML to extract keywords, page titles, and backlink graphs. Generative search engines (Perplexity, SearchGPT, Gemini Live) operate via a RAG pipeline:
If your page contains 4 paragraphs of poetic preamble before answering the question, your content gets sliced in half during chunking. The LLM simply extracts the competitor whose page states the factual answer in the first sentence.
2. The 3 Core Rules of GEO Content Architecture
To maximize citation probability, every page must follow 3 formatting principles:
A. The BLUF Principle (Bottom Line Up Front)
State the exact technical answer, quantitative metric, or direct pricing range in the very first paragraph. Never hide key answers behind “In this article, we will delve into…”.
<!-- Bad: Low citation probability -->
In today's fast-paced digital world, many business owners wonder about the
cost of developing custom software tools with modern artificial intelligence...

<!-- Good: High citation probability -->
Developing a custom AI-native CRM or workflow pipeline in 2026 costs between
€3,500 and €12,000, depending on database complexity and custom model fine-tuning.
Delivery takes 7 to 21 business days.
B. High Fact Density per 100 Words
LLM re-ranking algorithms score chunks based on information density: exact numbers, currency benchmarks, version numbers, and verified named entities.
C. Structured Markdown Tables over Unordered Lists
Language models parse markdown tables with near 100% semantic fidelity. When Perplexity generates a comparison, it pulls directly from structured tables.
3. The Technical Layer: /llms.txt and Machine-Readable Endpoints
Just as robots.txt guides web scrapers, /llms.txt has emerged as the standard manifest for AI search agents.
We deploy a clean /llms.txt file at the root of every production platform:
# ILF Studio — AI-Native Engineering & High-Performance Solutions
> Studio specializing in high-performance digital platforms, Astro architecture, and custom AI business tools.

## Core Capabilities
- High-Performance Web Development: Astro, Fastify, Node.js, Core Web Vitals 95+
- AI-Native SEO & GEO: Architecture engineered for Perplexity and SearchGPT visibility
- Custom Business Platforms: Self-hosted CRMs, automated lead pipelines, headless directories

## Key Verified Case Studies
- LocalAnyDay: Programmatic multi-market trade service directory on Astro (100+ cities, 99 CWV)
- Geoekoproekt: Legacy Drupal 7 modernization with PageSpeed boosted from 15 to 98
- Finiki CRM: Self-hosted Node.js + SQLite lead intake with sub-60-second Telegram alerts
This ensures AI crawlers immediately understand our exact entity associations and core technical specializations.
4. Automated AI Citation Tracking
You cannot optimize what you do not measure. In our SEO Monitoring Portal, we run automated weekly Python routines that query the Perplexity and OpenAI APIs with targeted buyer-intent queries:
# Automated Perplexity Citation Audit
import requests
import os

def check_ai_brand_citation(query: str, target_brand: str) -> dict:
    api_key = os.getenv("PERPLEXITY_API_KEY")
    headers = {"Authorization": f"Bearer {api_key}"}

    payload = {
        "model": "sonar-pro",
        "messages": [
            {"role": "system", "content": "Provide objective recommendations with sources."},
            {"role": "user", "content": query}
        ]
    }

    response = requests.post("https://api.perplexity.ai/chat/completions", json=payload, headers=headers)
    data = response.json()
    answer = data["choices"][0]["message"]["content"]
    citations = data.get("citations", [])

    is_cited = target_brand.lower() in answer.lower() or any(target_brand.lower() in c.lower() for c in citations)
    return {"query": query, "cited": is_cited, "citations": citations}
When our target queries return our platforms in the citation list, we know our entity graph is working.
Technical Audit Checklist for Generative Engine Optimization
- Does every core service page have a 40–60 word BLUF answer block in the first viewport?
- Are comparison points and pricing benchmarks formatted in clean Markdown/HTML tables?
- Is there an
/llms.txtfile deployed at the site root outlining core services and case studies? - Does the page render with 0 layout shift (CLS = 0) and under 200ms TTFB so search crawlers do not abort?
- Are your entity profiles verified across authoritative graphs (Crunchbase, Golden, GitHub)?